
dsh-force-compact
Aggressive, local-first context compaction for DeepSeek Harness agents.
A DSH Cordis function plugin that keeps the agent's working context lean by design: serve Qwen3.8‑27B on a self-hosted llama.cpp with a modest context, and the plugin shrinks the conversation itself — a large-window feel with no API cost and no data egress.
Why
- Self-hosted inference — the agent talks to a local OpenAI-compatible llama.cpp server
through the standard DeepSeek adapter; no separate adapter needed.
- Low context, high signal — instead of fighting a small cap, the plugin shrinks the
conversation, so the agent reasons over a tight prompt while keeping deep memory in the compressed head.
- Think off for compactions, passthrough everywhere else —
disableThinking: true
(default) turns thinking off on *this plugin's own compaction summarization call only*; every other model request rides the machine's configuration unchanged.
- Private & free — no per-token billing, no egress.
What it does
Two compaction engines coexist behind one facade (resolveCompaction), transparent to callers:
| Engine | Used when | Notes |
|---|---|---|
| Official | the compaction service resolves in the agent realm | Preferred; delegates to compaction/basic. |
| Builtin | automatic fallback (typical standard preset isolates the service) | Self-contained persistent transaction on ctx.sessions / ctx.llm.stream / ctx.tokenMeter; reuses the official compaction/* event vocabulary, so it replays safely across builds. |
No toggling — official wins when reachable, builtin takes over otherwise.
Trigger points
- Per-request guard (
agent/pre-step) — reads the session's *projected* context tokens
(the exact number the harness renders bottom-right). At autoThresholdTokens it rejects the outgoing request and compacts the head instead, retaining the latest retainLatestTokens verbatim. Below the threshold the request proceeds.
- Turn end / idle (
agent/status→idle) — when the agent quiesces, optionally
compacts via compactNow (gate: turnEndForceCompactionEnabled).
- Manual
/force-compact— immediatecompactNowwhen idle; when busy it queues a
process-local flag consumed at the next model step. Loaded lazily — see "Command availability" under Install.
session/flush— the awaited durability checkpoint.
Every path funnels into the single *"compaction result landed in the session"* boundary — the same point where the LiveUI signal fires.
Decision key is projectedTokens (provider-anchored, same figure as the UI corner), so the plugin never drifts from what you see; the threshold-aware shrink gate skips summarizer calls that provably cannot pull the session below the threshold (kills the low-threshold dead loop).
The builtin transaction bills shadowedTokenCount from the same tokenMeter.measure per-node prices the official engine uses, so the meter's collapse protocol settles the drop correctly — the bottom-right counter goes *down* after compaction.
Thinking control: scoped to compactions
Since the 2026-08 semantics revision, disableThinking controls one thing: whether this plugin's own summarization call (engine/builtin.js → engine/summarizer.js → ctx.llm.stream) carries reasoningEffort:'off'. Everything else is untouched:
| Call site | With disableThinking: true |
|---|---|
| Builtin-engine summarization call | Carries reasoningEffort:'off' |
| Every other model request (business, sub-agents, tools, other plugins) | Machine's LlmCallConfig unchanged |
Official compaction service calls | Not routed through any plugin seam — unaffected |
When the target is a llama.cpp / OpenAI-compatible endpoint, the thinking: { type: 'disabled' } field the adapter emits is silently ignored there — so the summarizer ALSO stamps the llama.cpp-native top-level reasoning_effort: "none", gated on the exact same condition. One options object carries BOTH fields:
| Endpoint family | Reads | Result |
|---|---|---|
| Real DeepSeek API | reasoningEffort:'off' → thinking:{type:'disabled'} | Thinking off ✅ |
| llama.cpp / OAI-compatible | reasoning_effort:"none" (top-level) | enable_thinking=false ✅ |
Each family tolerates-and-ignores the foreign key, so emitting both is harmless. The field is stamped in src/engine/summarizer.js (immediately before llm.stream(options)), NOT in the llm/stream waterfall — a prior draft injected there but proved ineffective structurally (middle-layer returns are discarded; in-place seed mutation crashes the host); see the src/hooks/wire-rewrite.js module header for the write-up. That hook now serves only the LiveUI watermark role.
Need thinking off on business calls too? Set your provider's reasoningEffort at the request-header level — the plugin deliberately stays out of that decision.
Observability: per-attempt audit lines
Every summarization attempt logs two lines (visible at the default debug: true) — the durable proof of the scoping decision and its wire fields, without capturing traffic:
[force-compact] <sessionId>: compaction thinking-policy — settings.disableThinking=true → extra.reasoningEffort='off' (this summarization call carries thinking-OFF)
[force-compact] <sessionId>: summarization wire-fields → <provider>/<model>: reasoningEffort='off' + reasoning_effort="none" (llama.cpp-native wire field)- Line 1 (
engine/builtin.js) records wheredisableThinkingis read and routed into
the call options; with the setting off it records *machine default*.
- Line 2 (
engine/summarizer.js) records both wire fields exactly as they leave the
options object, plus resolved provider/model; unstamped fields are labeled (absent…).
Empirically grounded: probed against a local llama.cpp endpoint, a baseline request returned populated reasoning_content (the model thinks by default), while the same request with top-level reasoning_effort:"none" returned none at all — the field genuinely disables thinking there, and business calls (which omit it) keep thinking.
LiveUI status
A tiny host→client messenger (the liveUi settings field mirrored live to the browser) pins a badge beside the turn:
- Red "compressing" — just before a compaction commits (screen text is Chinese);
- Green "done" — the instant a compaction lands; 3 s later a fresh random working line
takes over;
- Blue "working" — otherwise a rotating playful one-liner;
- Cleared at conversation end — when the agent goes
idle(the turn is fully
done), an empty text (isImportant) is pushed: the badge text is wiped and the phase color removed, restoring the official look. Replaces the former conversation-START forced working-pair override (removed 2026-09).
Publishers are fail-safe: a messenger glitch can never disturb the actual compaction.
How it works
agent/request(payload, next)              # every model request
    return await next()                  # pure pass-through (thinking-off scopes
                                          # ONLY to the plugin's own summarizer)

agent/pre-step(payload, next)             # before each model step
    projectedTokens >= autoThresholdTokens?
        no  -> next()                     # let the request proceed
        yes -> compactRegion(head-before-retainLatestTokens, signal)
               return { kind: "reject" }  # no model request this step

agent/status({ agent, status })          # lifecycle transition
    status === "idle" && turnEndForceCompactionEnabled?
        -> compactNow(agent, freshSignal) # turn-end compaction

session/flush(session)                   # durability checkpoint
    select region -> project messages -> preview + shrink gate
    -> compaction.compactRegion(start, end, agent, signal)
Supporting modules:
src/hooks/guard.js—agent/requestpure pass-through +pre-stepthreshold gate +
process-local force flag (thinkingDisabled survives only as a legacy predicate).
src/hooks/command.js— the/force-compactcommand (lazily registered).src/hooks/idle.js— turn-end forced compaction.src/hooks/wire-rewrite.js— thellm/streamLiveUI watermark hook (no wire manipulation;
historical note in the module header).
src/engine/region.js— head/tail-anchored region selection (with the official pairing ledger).src/engine/summarizer.js— the one-shot LLM summarizer, fully aligned with official
compaction-basic (target resolution, prefix-cache alignment, purpose:'compaction' tag, fail-closed finish classification, usage capture).
src/engine/builtin.js— the builtin persistent transaction (officialcompaction/*vocab).src/engine/checkpoint.js— preview + shrink gate + delegation to the compaction service.src/core/projected.js— provider-anchoredprojectedTokens.src/core/ui-signal.js— the LiveUI messenger.
Install
As an installable package (recommended):
# from npm (published):
npm install @falling-ts/dsh-force-compact
# from git:
dsh plugin --profile web add github:falling-ts/dsh-force-compact
# from a local checkout:
dsh plugin --profile web add ./dsh-force-compact
Or, from a local checkout, as a --patch overlay without installing:
dsh web --patch dsh-force-compact/cordis.patch.ymlThe plugin is loaded iff ~/.dsh/logs/dsh-force-compact.log gains:
[force-compact] debug logging enabled — writing [force-compact] lines to <absolute path>Command availability — /force-compact loads lazily
The commands service arrives with the agent-presets plane, after the plugin's boot-time apply, so registration happens at the first guarded-listener activation (agent/request / agent/pre-step / agent/status / session/flush), settling permanently on the first success. Practical effect: after (re)starting the instance, a fresh session's / picker does NOT show /force-compact until that session makes its first model request — send any one message, then the command is registered process-wide.
- Success:
[force-compact] /force-compact command registered (deferred) commandspermanently absent: one… still UNREGISTERED 10 min …warn explains the
empty picker. Until registered, the rest of the plugin works — degradation, not an install failure.
Verify a compaction happened:
idle compaction (builtin) shadowed N nodes (~M tokens)
builtin compaction OK — replaced span seq[A..B] (N nodes, ~K tokens) with a P-char checkpoint
compaction thinking-policy — settings.disableThinking=true → extra.reasoningEffort='off' (…)
summarization wire-fields → <provider>/<model>: reasoningEffort='off' + reasoning_effort="none" (…)
(The last two lines are the per-attempt audit pair described under "Observability".)
Settings
$DSH_HOME/settings.yaml, namespace falling-ts-force-compact:
| key | type | default | meaning | |
|---|---|---|---|---|
disableThinking | boolean | true | Only the plugin's own summarization call carries reasoningEffort:'off'; everything else unchanged. | |
autoThresholdTokens | number ≥ 32000 | 32000 | Projected-token trigger for the gate. Floor 32000 (clamps back up at read time). | |
retainLatestTokens | positive int ≥ 8000 | 8000 | Retain the latest N tokens verbatim; older history is summarized in one batch. Floor 8000. Drives both the auto gate and /force-compact. | |
turnEndForceCompactionEnabled | boolean | true | Compact on the agent's idle transition. | |
debug | boolean | true | Emit [force-compact] diagnostics to the plugin log. | |
logFile | string | ~/.dsh/logs/dsh-force-compact.log | Diagnostics destination (~ expands to home dir). | |
compactionMode | `'realm' \ | 'global'` | 'realm' | Official-service resolution strategy (priority-1 path). |
builtinEnabled | boolean | true | Gate for the builtin engine fallback. | |
maxSummaryTokens | integer (1024–200000) | 1024 | Cap on the summarizer LLM maxTokens. |
Example — an aggressive local profile:
falling-ts-force-compact:
  disableThinking: true
  autoThresholdTokens: 40000   # compact sooner ⇒ keep the live prompt small
  retainLatestTokens: 8000
  turnEndForceCompactionEnabled: true
Without the settings service the plugin falls back to the same defaults and still compacts — the namespace is optional, never a hard dependency.
Tuning for low-context llama.cpp
Keep autoThresholdTokens comfortably below the served context: the live prompt stays small and latency flat, while the agent keeps deep memory through the compressed head. Pressure is measured in *projected* tokens (provider-anchored), so the threshold maps predictably onto the UI figure.
Behavior notes
- Runtime dependency: the
compactionservice (preset plane
agent-presets:compaction-basic), read live via ctx.get('compaction'); unreachable → the builtin engine takes over (or the request proceeds).
- Optional dependencies:
settings/tokenMeter/commands/llm/agentsare
read via ctx.get(...) with guards — a missing one degrades gracefully.
- Per-request settings read: parameters are read every model request, so edits take
effect on the next request without a restart.
- Signals:
agent/*Waterfalls forward the current turn's signal; thesession/flush
checkpoint and the agent/status idle listener each mint a fresh AbortController.
- Persistence: durable output is the
compaction/*bracket events + a
surfaceOp:replace user/message checkpoint, replay-safe across builds.
- Client half:
web/client.jsadds the settings section "Force Compact" (localized
labels), live-editable without restart (uSES-safe mirror).
- One intentional timer: the 3 s
publishDonefallback (presentation-only, documented
deviation). Otherwise the plugin is pure listeners + a process-local Map force flag.
Screenshots
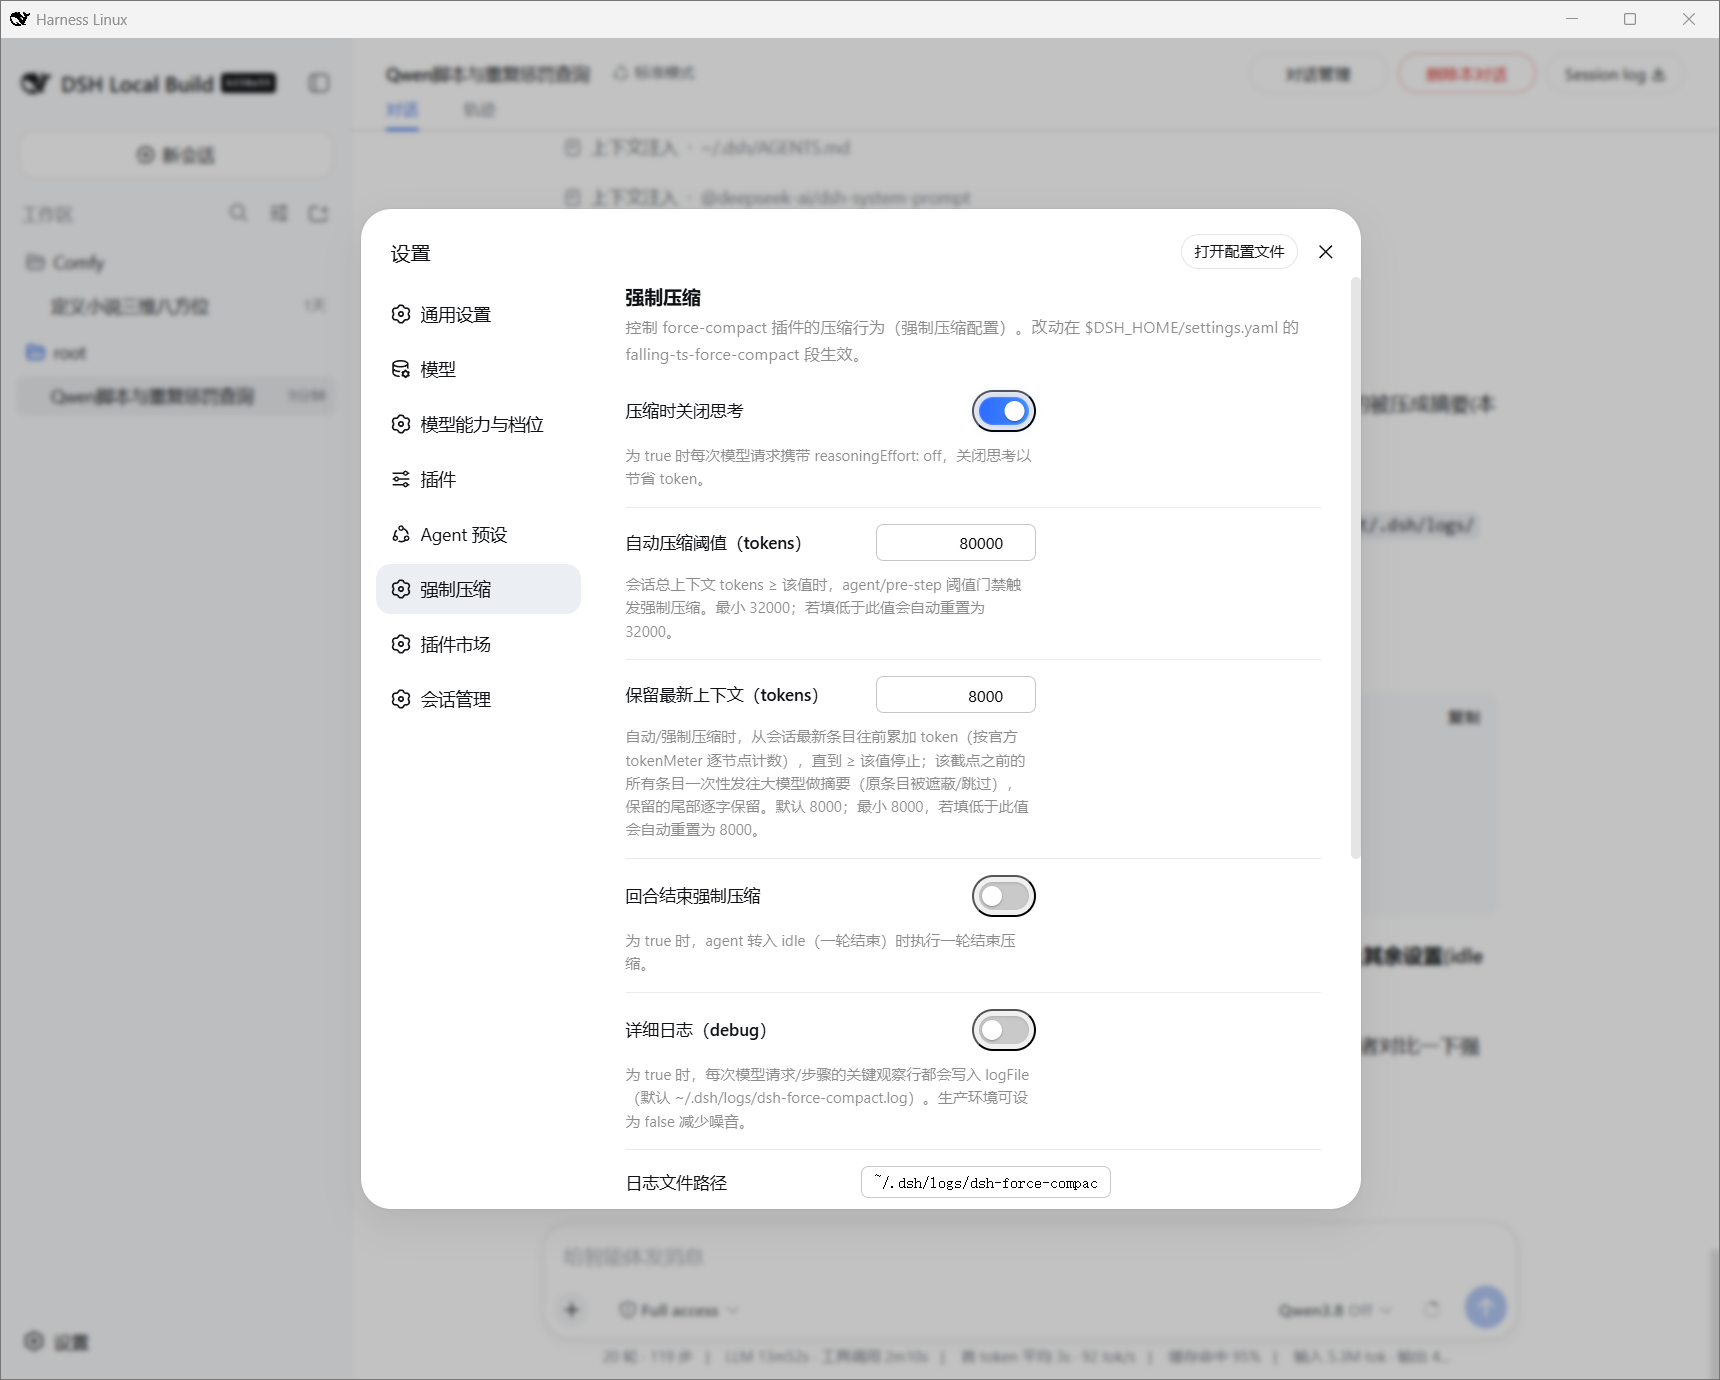
*Settings page — the Force Compact section; all nine fields above are editable live without a restart.*
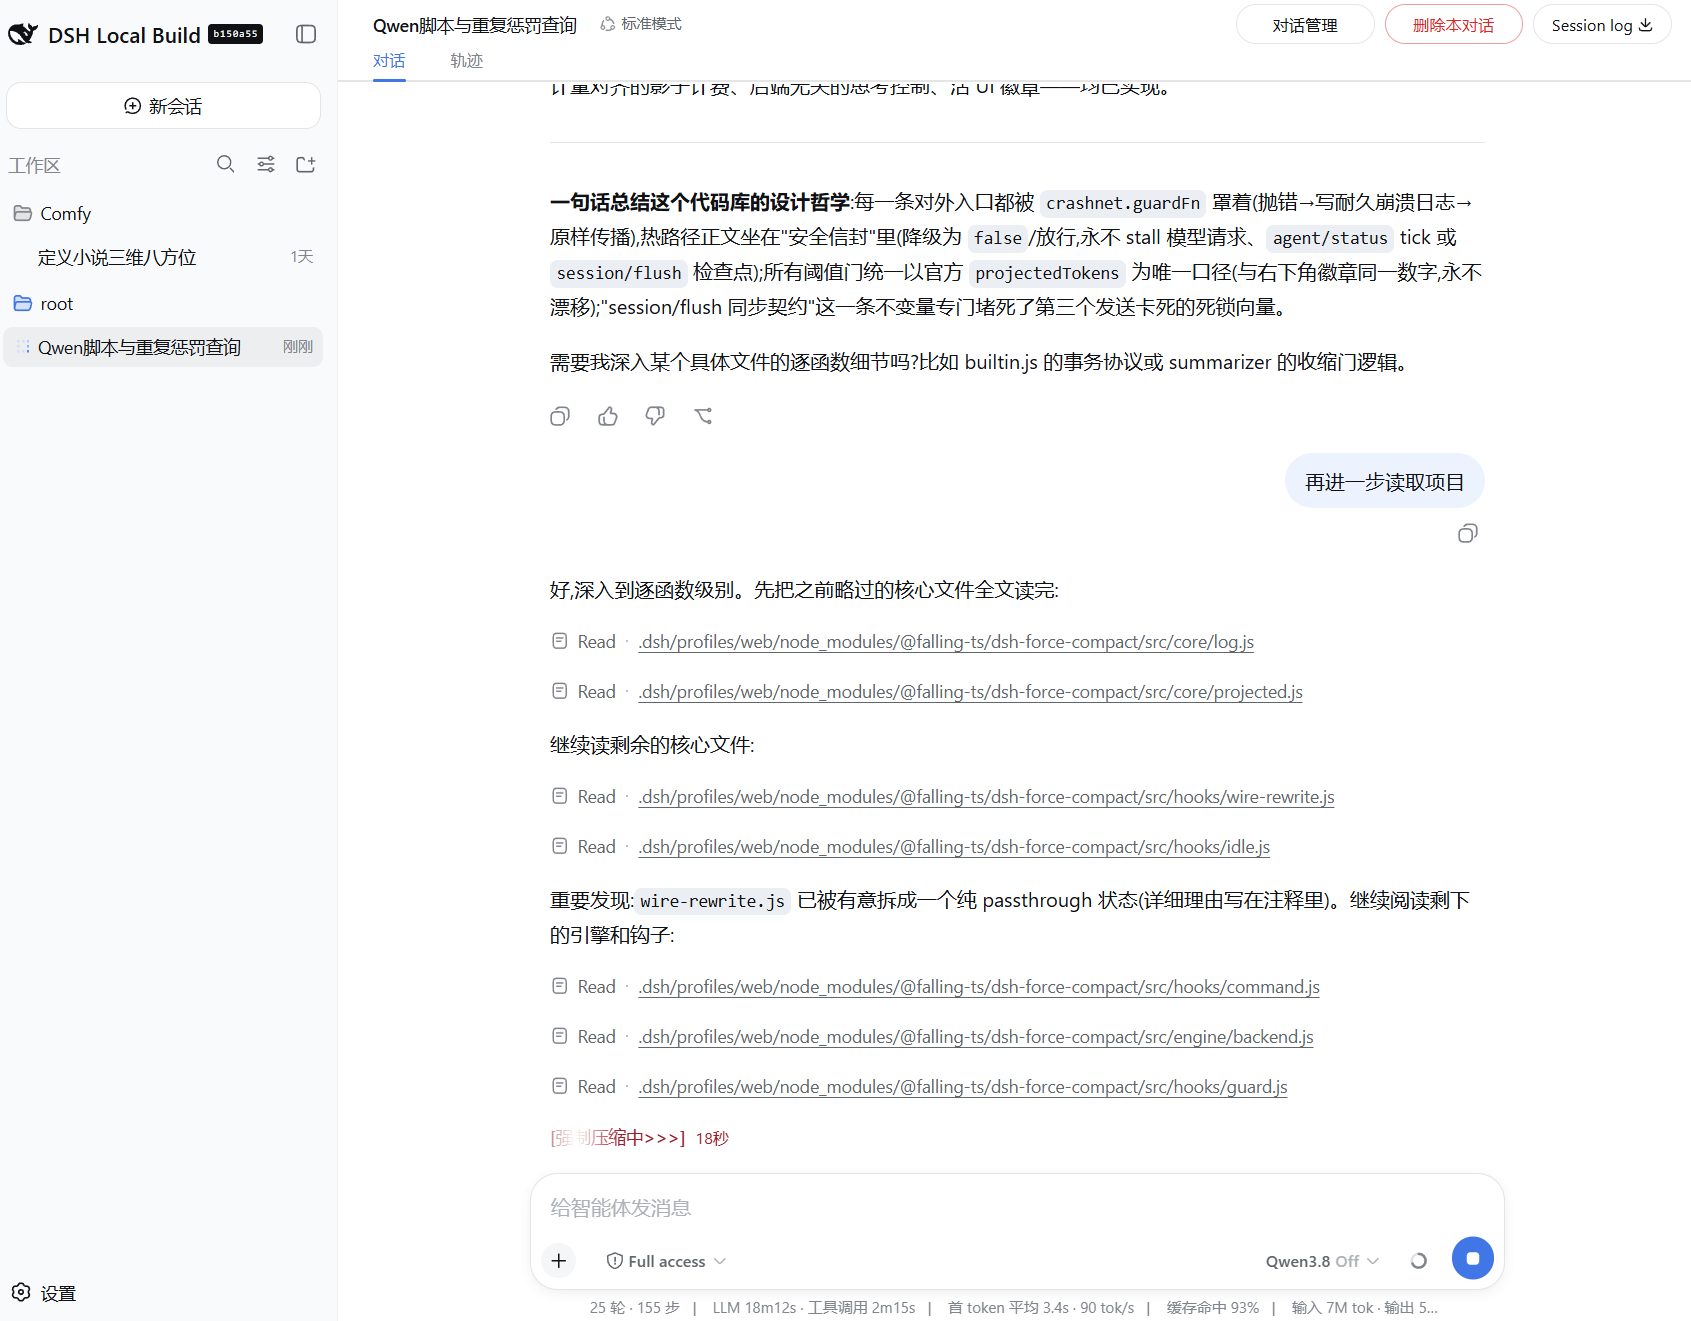
*Conversation page — the LiveUI signal paints three states (red: compressing / green: done / blue: working); the green banner fades after about 3 s back to a random working line; at conversation end the badge is cleared (empty text) back to the official look.*
License
MIT (see LICENSE).
