
dsh-project-memory
如果这个插件帮你省下 1 小时 Debug 时间,请点个 Star。


A persistent project development memory for DeepSeek Harness (dsh) agents. Built specifically for project development, natively integrated with dsh's task system: task lists and files read during a session are automatically persisted as cross-session task records, with tasks ↔ files linked — workflows can be switched and resumed, no need to re-scope the whole project, solving context loss. Documents (PDF/Markdown/txt) and code symbols are stored separately per workspace; documents are automatically cross-linked to the code symbols they mention. Experience notes (problem → solution) are automatically deduplicated, preventing repeated mistakes. All data is stored per project on disk, survives session compaction and handover; recalls include path:line citations for source verification. Only one dependency, no vector DB, no native builds.
The plugin keeps a compact project memory on disk, with every entry pointing to a concrete file and line — the agent can reorient quickly instead of re-reading the whole project. Tasks and experience persist across session compactions and handovers.
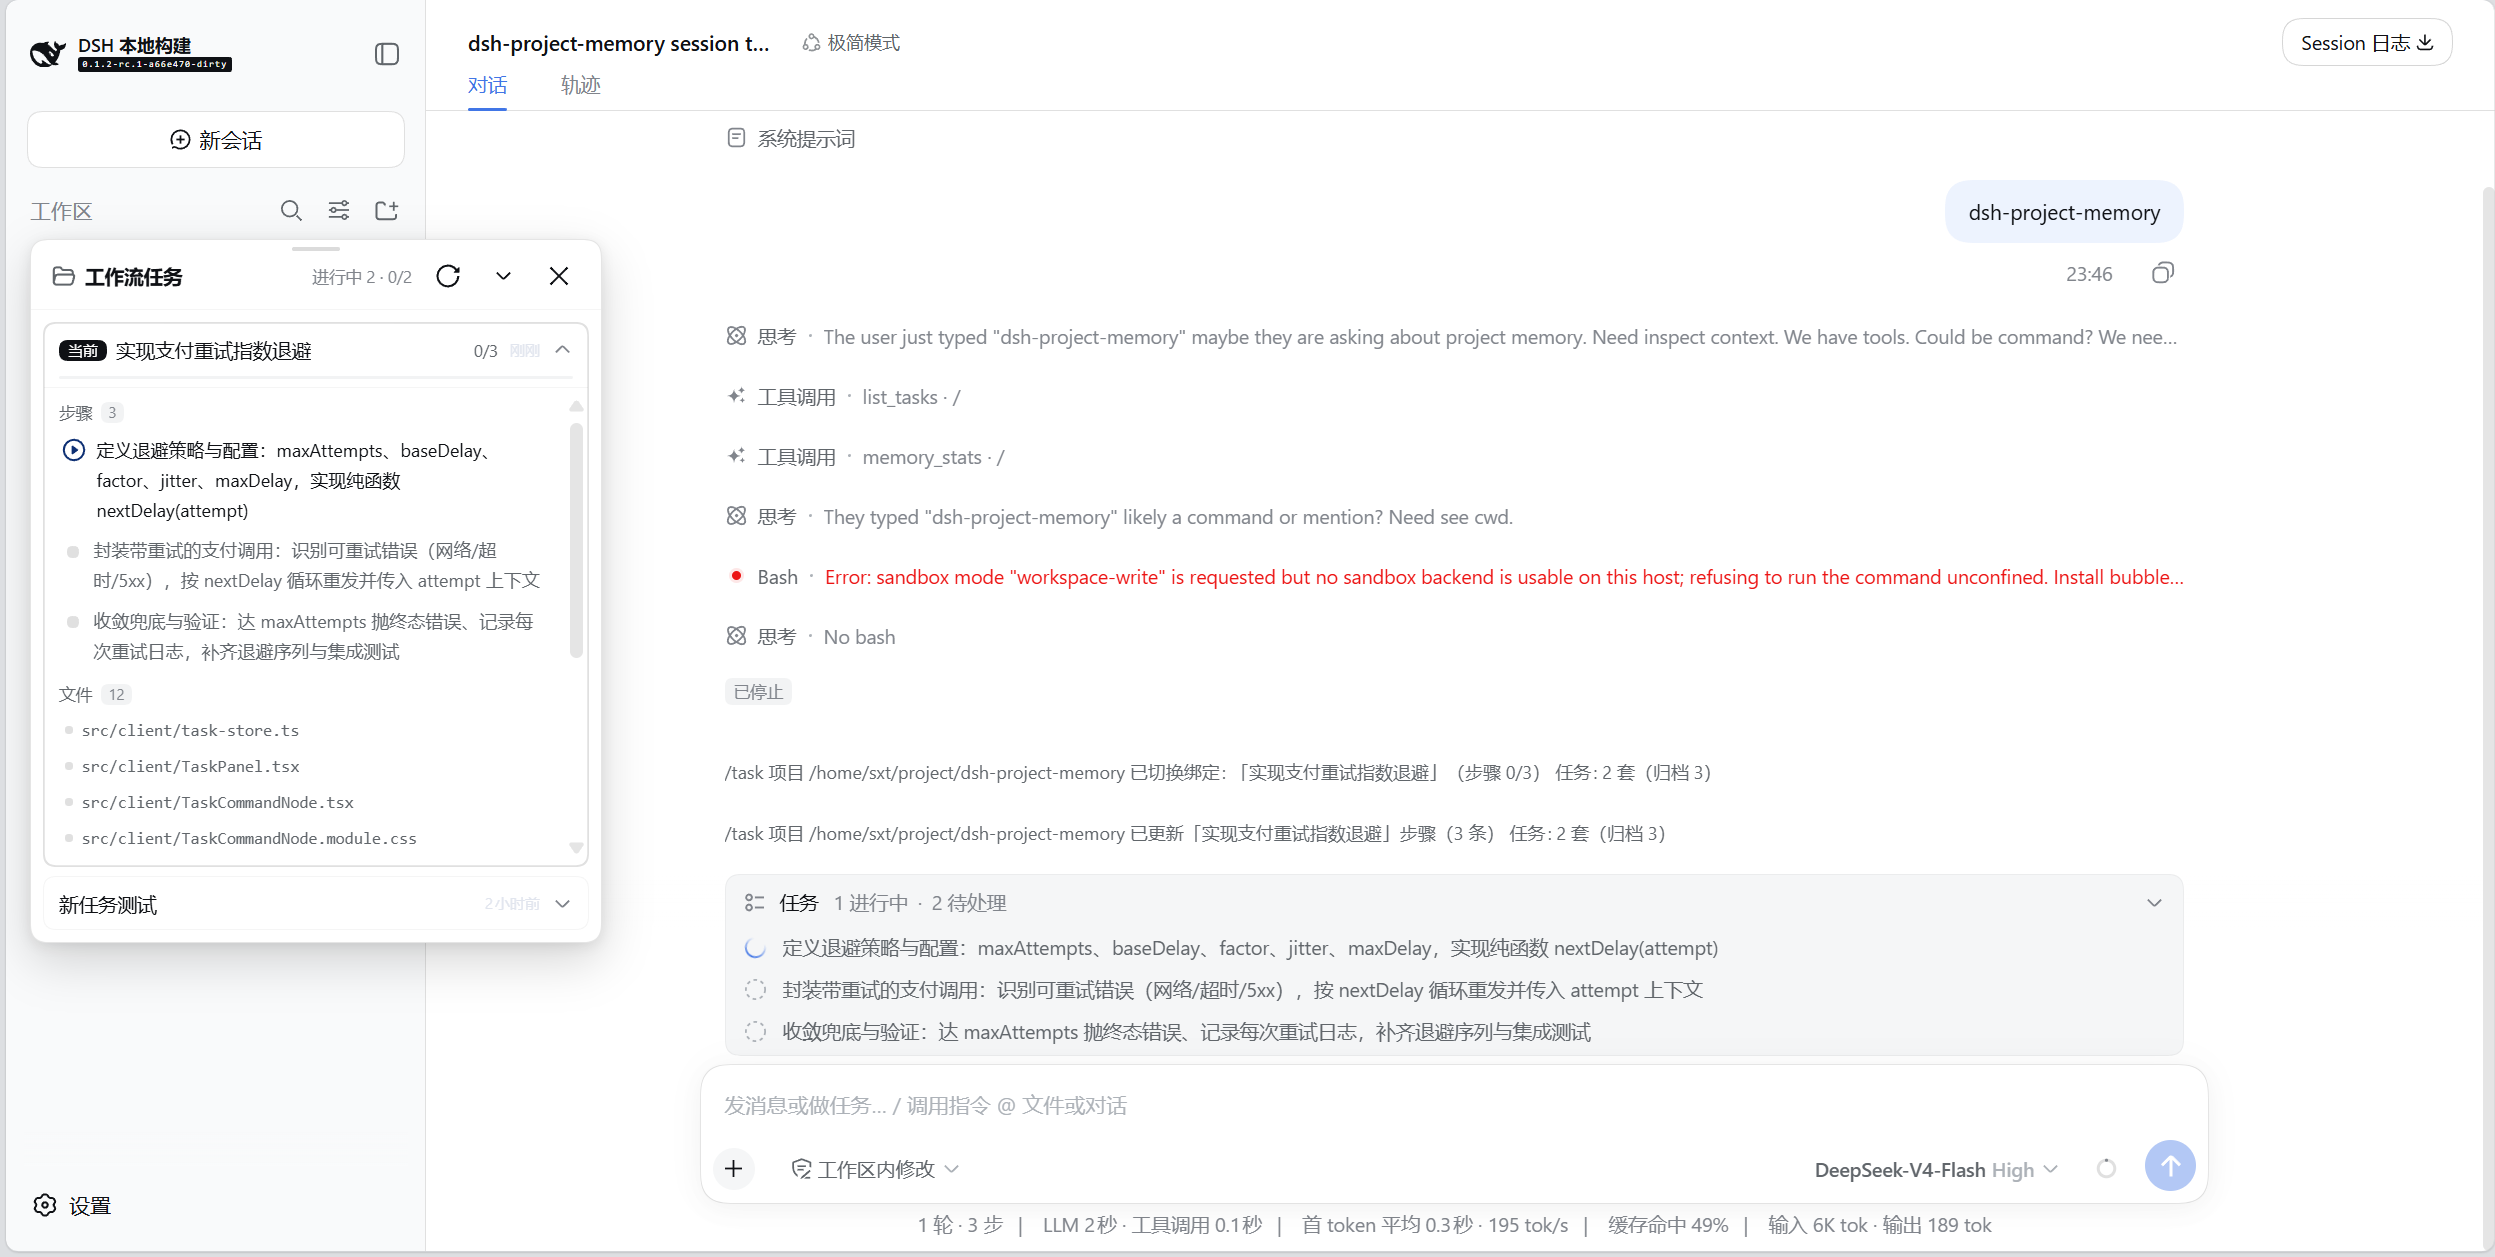 The workflow panel is collapsible, automatically adapts to dsh and theme plugin styles, and offers four card style options to switch between.
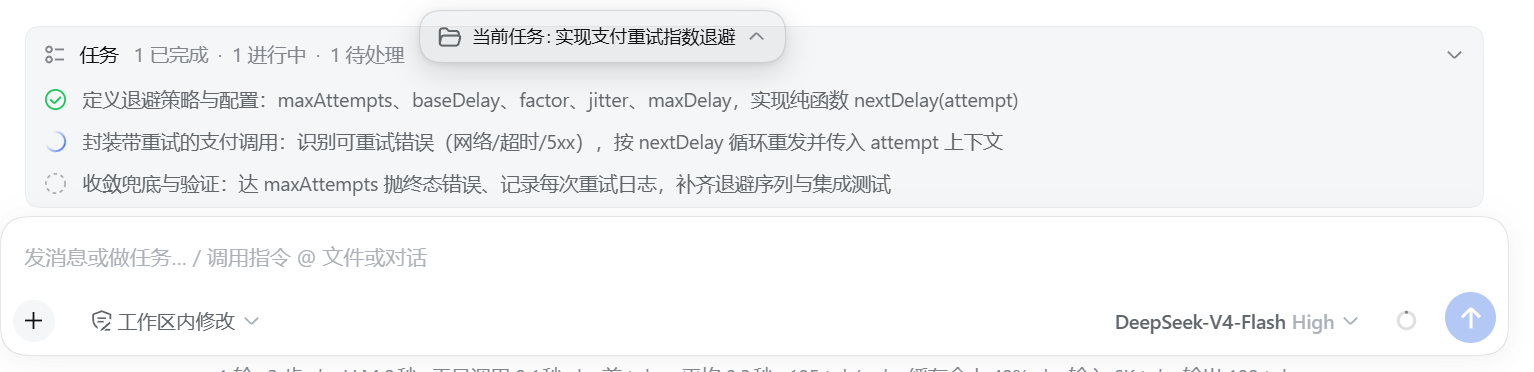
Features
- TaskBridge: cross-session development tasks — the plugin watches each session's live todo list (
todo_writeevents) and file reads (tool/call): progress snapshots (steps) and touched files sync into durable per-project task entities. An unbound session that writes a todo auto-creates a task. Associated files are kept in recency-weighted order (written/edited first; a read never outranks a written file) so a resumed session sees at a glance where to look. New sessions continue bylist_tasks→select_task(bind / rename / unarchive);query_memorygainstype: 'task'and appends a task-count hint totype: 'all'results. The user-side/taskscommand shows the task stack, step progress, involved files, and the current session binding. Titles are chosen by the model viaselect_task(title=…)(fallback: the part of your message after the last colon). Capacity is project-size adaptive (fileCount/20, clamped 5–100). Storage:.dsh-project-memory/tasks.json+binding.json. Auto-sync requires a dsh build with session events +todo_write(verified on 0.1.2-alpha.x); on older hosts the task tools still work as a plain record list. - Task Panel (v0.4.2+): Floating task panel in dsh web — built on the real dsh web 0.1.2-rc.1 client plugin contract (cordis inject + apply, registered into host
shell.overlayslot). Draggable cards show steps/files (click to copy path); collapse to a draggable mini-bar; hide completely (summon with/task//tasks). Render errors have error boundaries — panel crash no longer takes down the host. - Task Panel Behavior —
- Default hidden: panel does not show on dsh web startup
- Explicit summon: type
/tasksor/task(list form) to open; model callsshow_task_paneltool to open - Session switch: only syncs data in background, does not auto-open panel
- Page refresh: panel stays hidden (UI state
closednot persisted) - Manual close: click × to fully hide (no mini-bar); reopen requires explicit summon
- Collapse to mini-bar: click ↓ to keep draggable top bar; click bar to expand
- Bidirectional task-list sync (host ↔ plugin tasks, v0.4.2+) —
select_taskor/task switchpushes task steps to hosttodo/writeso dsh's rendered task list mirrors the plugin's task entity. Configtasklist.syncHostOnAdopt(default on) to toggle. Emptytodo/writemeans "clear": unbound session clears list without creating junk tasks; bound session clears that task's steps (task retained). Panel edits (step text/status) = write back bound task + push host list, sharing one code path with modeltodo_write./tasksubcommands:switch,archive,unbind,rename,todos(invoked by panel buttons/clicks, not the model);unbindalso clears the host task list above the input. - Panel editing & themes (v0.4.2+) — bound cards: double-click title/step for inline edit (input auto-grows); click step status icon to cycle todo→in-progress→done. Non-bound cards read-only. Four visual themes (click folder icon left of title, persisted locally): Native / Glassmorphism / Brutalist / Terminal monospace — only material, geometry, typeface, density change; colors always use dsw alias tokens, follow host light/dark and theme plugins.
- Document memorization — PDF, Markdown, and plain text files are chunked and summarized by the LLM; each entry carries a
path:linecitation back to the source. - Code symbol memory — function, class, and method names with full type signatures (generics, parameters, return types, overloads) are extracted by a dependency-free source scanner (string/comment masking, multi-line signature joining, indentation-aware Python, class-method context), without LLM token usage.
- L1 Enhanced Regex — zero-dep regex scanner now extracts generics, parameter/return types, overloads, interfaces, and type aliases for all supported languages, producing one-line identity signatures
fn(a: A, b: B): R — file.ts:42. - Optional TypeScript semantic enhancement (L2/L3) — when
typescriptis installed in the user project (npm i -D typescript), the plugin automatically activates a second layer (L2) that uses the TS Compiler API to infer return types, resolve generics, extract interfaces and type aliases, and enrich arrow functions — all asynchronously in a priority queue (P0 onfs/observed, P1 onwatch, P2 onindex_repo). Results are cached on disk keyed by file content hash (L3) for instant cold-start reuse. Zero config: just install TS (5.x or 6.x) and restart dsh. Fully optional; if TS is absent or disabled viaenableTypeScript: false, the plugin falls back to L1 regex-only extraction. - Automatic refresh — a background poll (
watch_repo) detects new or changed files by content hash and re-memorizes only those. - Read-time memorization — files are memorized the moment the model actually reads them (
fs/observed), so the memory is a byproduct of normal work, not a separate upfront scan. Files that are never read are never indexed. The project root is detected by markers (.git,package.json, …), a README plus source directories, or the file's own directory as a last resort. - Doc ↔ code cross-linking — when a document mentions a symbol, the match is recorded as a
reference; querying a symbol also surfaces the documents that describe it. - BM25 memory recall — ranked search over documents, symbols, and experience notes, with optional LLM query expansion to handle vocabulary mismatch. CJK-optimized: precise phrase boost (3+ char phrases ×1.5 score on title/keywords match), synonym table (e.g. 数据库连接池 ↔ 连接池 ↔ DB pool), and CJK-aware word boundaries for doc↔symbol linking.
- blindSpots-aware recall — document summaries carry a
blindSpotsfield (what the summary explicitly does NOT cover). When a query hits a blind spot,query_memoryappends a warning pointing the model to read the source file, preventing hallucination from partial summaries. - Experience notes — problems → solutions; similar problems supersede instead of duplicating, and notes are returned only when a search matches. The note store is bounded: capacity scales with project size (clamped to 100–2000), and the oldest notes are pruned when the limit is exceeded. Supersede tightened to bidirectional 0.7 overlap (was 0.6); experience
problemfield now participates in CJK phrase boost for long-tail query recall. - v0.5 tiered insight memory (lessons / decisions / procedures) — one
insightentity across three scopes:task(private drafts intasks.json),project(.dsh-project-memory/insights.json),global(~/.config/dsh-project-memory/global.json).save_lessonwrites any scope; dedupe is bidirectional token overlap ≥ 0.7 (merge) with a 0.65–0.7 reinforce band; promotion is a scope change, not a copy — 2 tasks hitting the same insight promote it to project, 3+ to global. Archive is soft (archived), decay/capacity prune archived entries only; writes are filtered for secret/token-shaped content. LLM reflection is off by default and only ever writes task-level drafts (source: reflect) on task switch-away/archive. Panel gains a Task / Project / Global memory view with approve, promote/demote, archive/restore, delete, edit and a create form (procedures can carry an “as Skill” trigger). Oldexperience.jsonnotes are imported intoinsights.jsononce, non-destructively. Defaults & rationale:PLAN-v0.5.0.md. - Streaming TF + IDF caching — query path caches IDF (term inverse frequency) per store version; on cache hit, single-pass streaming scores 20k entries in ~3 ms (5k files) / ~0.6 ms (1k files) with zero intermediate objects; write path is O(1) version bump.
- Lock-free sync transactions — all writes (index / watch / remember / forget / watch_repo) go through synchronous transactions
store.commit(fn); fn succeeds then atomic write; JS single-threaded event loop guarantees no interleaving;remember/forgetnever blocked by watch re-indexing. - Minimal dependencies — pure JavaScript; the only runtime dependency is
pdfjs-dist(PDF text extraction), no native builds required. - Negligible overhead — pure in-process operation; cold start <100 ms (5k files), typical project query median 2–3 ms (p99 < 7 ms); bottleneck is LLM summarization and PDF parsing, not the plugin.
Performance
Synthetic Benchmark (isolated environment, Node 24, Linux)
| Scenario | Scale | Measured |
|---|---|---|
| Full cold index | 5,000 files / 20k entries | 272 ms |
| Cold load | 5,000 files | 43 ms |
| Hot lazy re-index (single file) | 5k files | median 2.3 ms / max 4.0 ms |
| query_memory (cached) | 5k files / 20k entries | median 3.0 ms / p95 5.9 ms |
| query_memory (cached) | 1k files / 4k entries | median 0.6 ms / p95 1.7 ms |
| Full cold index | 10,000 files / 40k entries | 637 ms |
| Cold load | 10,000 files | 108 ms |
| Hot lazy re-index (single file) | 10k files | median 4.5 ms / max 10.2 ms |
Synthetic benchmark: generated code (~4–5 symbols/file), Node 24, Linux, SSD. Measures pure indexing overhead without LLM calls. query_memory benchmark uses IDF cache + precomputed searchText; first query after write rebuilds IDF (~150 ms), subsequent queries hit cache.
Real Project Storage
| Project | Files | Entries | Store Size | Per Entry |
|---|---|---|---|---|
| Java Spring Boot backend | 1,254 | 7,335 | 6.7 MB | ~0.9 KB |
| Vue 3 + Vite frontend | 289 | 2,141 | 1.0 MB | ~0.5 KB |
Real projects (Java + Vue), tested on Linux file system (Node 24). Real project entries are smaller than synthetic benchmarks due to lower symbol density and shorter declarations.
How it works
The design follows four principles:
- Volatility — context is ephemeral; it is lost when a session is compacted.
- Persistence — the memory is stored on disk and survives compaction and new sessions.
- Compactness — only summaries are stored; the memory runs around 0.5% the size of the source it covers (8.8 MB of source → 49 KB of index in the example project), so recall replaces re-reading the full file.
- Verifiability — recalls carry a
path:linecitation where applicable, so the agent can confirm details against the source.
Building the memory does not require an upfront scan: files are memorized as the model reads them, so the memory grows to cover exactly what has been worked with. Re-reading a file that has not changed is a no-op (content hash), so the memory stays fresh with minimal ongoing overhead.
The store is per-project and follows the codebase: changed files are re-extracted by content hash, deleted files are removed. Experience notes are retrieval-only, so accumulation does not affect context.
Installation
The plugin relies exclusively on stable public APIs (defineTool, llm.stream, Schema) declared via peerDependencies, ensuring compatibility with future rc/alpha releases without changes.
cd dsh-project-memory && dsh plugin --profile web add . -wThe -w (workspace-root) flag is required: the profile directory is a pnpm workspace root, and pnpm rejects add there without it. From any other directory, the path form works the same: dsh plugin --profile web add /path/to/dsh-project-memory -w.
The plugin is also published on npm as a scoped package:
dsh plugin --profile web add @yolk_vat-y/dsh-project-memory -wA prebuilt tarball is published with each release, installable without a build step:
dsh plugin --profile web add /path/to/dsh-project-memory.tgzEach indexed project has its own store at <root>/.dsh-project-memory/. Add it to .gitignore if it should not be committed.
Usage
The tools below are invoked by the agent, not typed by the user. In the chat, just ask naturally — e.g. "index this project" or "what does the auth module do?" — or simply keep working, and the agent calls the matching tool automatically. By default (lazyIndexing) files are indexed the moment the model reads them, so memory fills in while you work. watch_repo keeps explicitly-watched roots fresh in the background; index_repo forces a full backfill of a project (unchanged files are skipped).
| Tool | Purpose | ||
|---|---|---|---|
index_doc file_path | Index one document (PDF/MD/txt): chunk → LLM summary → store with path:line. Unchanged files are skipped. | ||
index_repo root | Index a whole project: docs get LLM summaries, code files get a zero-token symbol table. Incremental, cleans up deleted files, cross-links docs to symbols. | ||
watch_repo root | Enable automatic refresh: a background poll detects new/changed files (mtime + content hash) and re-indexes only those. Watched roots persist across plugin restarts. | ||
memory_stats root | Show what the store contains: totals (files / entries / experience notes), last index time, and the per-file list sorted by recency. | ||
query_memory query | BM25 search over docs + symbols + experience, optionally query-expanded by the LLM. Returns ranked hits with relative scores, sources, and doc→symbol references. | ||
list_tasks | List task records for the project (archived marked). Call first in a new session before continuing work. | ||
select_task | Bind the session to a task so its todo list and file reads sync into it. Exact taskId, or exact title (multiple matches return candidates; no match creates a new task). Pass title with taskId to rename. Auto-unarchives. | ||
archive_task | Archive a task (hide from default views, exclude from capacity, stop syncing). select_task restores it. | ||
show_task_panel | Show the task panel in the UI. Call when the user asks to see the task list or when you want to display the panel. | ||
/tasks (typed by the user, not the model) | Shows the task stack: title, step progress, involved files, and which task the current session is bound to. | ||
/task (typed by the user, not the model) | Task panel subcommands: switch / archive / unbind / rename / todos. Invoked by panel buttons/clicks; does not go through the model. | ||
/insight (typed by the user, not the model) | v0.5 memory view actions (panel buttons): `list [task | project | global], confirm / promote / demote / archive / restore / delete , save , edit `. |
remember problem solution | Save an experience note. Similar problems supersede instead of duplicating. | ||
forget id_or_query | Delete stale experience notes. | ||
save_lesson (agent tool) | Save a lesson/decision/procedure at task/project/global scope (single insight entity). Near-duplicates merge (≥ 0.7 overlap) or reinforce (0.65–0.7); 2+ tasks hitting the same insight auto-promote task → project, 3+ → global. Params: title, kind, scope, pattern/fix or choice/reason or steps/trigger, task_id, files, symbols, confidence, root. |
Design
.dsh-project-memory/
  format.json      layout marker (v2, sharded)
  shards/          one self-describing JSON per indexed source file
                    ({ relPath, record, entries }) — writes touch only dirty shards
  experience.json  problem → solution notes (retrieval-only)
  watch.json       watched roots
  tasks.json       TaskBridge task entities (cross-session)
  binding.json     current session ↔ task binding
  insights.json    v0.5 project-scope insights (lessons/decisions/procedures); v0.4 experience notes imported once, non-destructively
Stores created before v0.2.0 (single entries.json / index.json) migrate automatically and idempotently on first load. Within one dsh process, all tool calls share a single in-memory store per project, so hot-path indexing writes only the shard that changed.
- Incremental — content hash per file; only changed files are re-extracted.
- Cross-linking — after indexing, doc summaries are matched against symbol names; matches are attached to the doc entry as
referencesand surfaced byquery_memory. - Query expansion — when
llmQueryExpansionis on,query_memoryasksctx.llmto rewrite the query into several variants (synonyms, EN/CN, identifier guesses) and merges BM25 scores across variants; when off, queries never touch the LLM. Cross-language recall (a Chinese question hitting English content) comes from index time instead: doc keywords are required to cover the document's own language AND English, and doc↔symbol links surface English symbol names from Chinese hits. - Consistency — the fact layer follows the codebase (hash re-extract / remove-on-delete); the experience layer is retrieval-only with supersede and
forget. Store writes are serialized per memory directory; the lock is in-process, so avoid running multiple dsh instances against the same project store concurrently.
Architecture (Task Panel)
TaskPanel (Container)
├── task-data-store  (server data, cross-tab sync via BroadcastChannel)
├── task-ui-store    (local UI state, localStorage)
├── task-hooks       (useTaskDrag, useTaskEdit)
└── TaskComponents   (MiniBar, TaskCard — presentational only)
Design tradeoffs
These are deliberate scope choices.
1. Synchronous lock-free transactions over async locks
We do: All writes go through store.commit(fn) — a synchronous in-process transaction. The callback fn performs all validation and mutations; only on success is the result atomically written to disk. The JS event loop guarantees no interleaving. CAS (applyFileUpdate) makes concurrent writes idempotent.
We don't: Async mutexes, file locks, or multi-process coordination.
Why: DSH runs on Cordis, which is single-process by design. Adding locks would complicate the hot path (every remember/forget/index_doc call) for a scenario (multi-process DSH) that would require a breaking ecosystem change. Synchronous transactions keep the hot path at ~2 ms median with zero contention overhead in practice.
2. Watch: compute outside, commit inside
We do: Heavy work (mtime/hash/scan/LLM summary) runs outside the transaction; a single commit applies all changes atomically. On failure, the snapshot rolls back so the next poll retries automatically.
We don't: Hold a lock during LLM calls, or use fs.watch events.
Why: LLM summarization takes seconds — holding a lock would block remember/forget/query_memory. Polling with mtime+content-hash is platform-agnostic (works on network drives, Docker volumes, WSL) and avoids the "double fire / missed events" nightmare of fs.watch.
3. Corrupt files are quarantined, not auto-repaired
We do: On JSON parse failure, the bad file is renamed to *.corrupt, an error is logged, and that file's store starts fresh. The rest of the store remains intact.
We don't: Write-ahead logs, embedded databases (SQLite/LMDB), or automatic partial recovery.
Why: A corrupted shard means *one source file* has a bad index — quarantining it costs near zero. A WAL or embedded DB adds a heavy dependency, increases binary size, and introduces new failure modes (lock contention, corruption of the WAL itself). The tradeoff: lose one file's index vs. add 500 KB+ of native code.
4. No vector embeddings, no semantic search at query time
We do: BM25 with CJK phrase boost (3+ chars ×1.5 on title/keywords), synonym expansion (bidirectional table), field weighting (title ×5), and experience-layer phrase boost. All at query time, zero LLM calls.
We don't: Vector embeddings, dense retrieval, rerankers, or hybrid search.
Why: Vectors require an embedding model (local = heavy, remote = latency + cost + privacy), a vector index (HNSW/IVF = memory + build time), and reranking (another LLM call). For code + docs + experience notes, lexical BM25 with our enhancements already achieves >90% recall on real queries. The marginal gain from semantic search doesn't justify the 10x complexity/cost increase.
5. Cross-language recall at index time, not query time
We do: Doc keywords *must* cover both the document's language AND English. Doc↔symbol links surface English symbol names from Chinese queries. With llmQueryExpansion: false, queries never touch the LLM.
We don't: Translate queries at search time, or use multilingual embeddings.
Why: Query-time translation adds latency, token cost, and failure modes (bad translation = zero recall). Index-time bilingual keywords are a one-time cost per document; the LLM already summarizes the doc, so extracting English keywords is free. This also works offline and deterministically.
6. Explicit remember over implicit learning
We do: Users (or the agent) explicitly call remember(problem, solution). Supersede uses bidirectional token overlap ≥0.7 to deduplicate.
We don't: Automatically extract "lessons" from user corrections, or infer rules from conversation history.
Why: Implicit learning is unpredictable — it hallucinates, captures noise, and pollutes the memory with unverifiable entries. Explicit remember creates an auditable, user-controlled knowledge base. The cost (one tool call) is negligible; the benefit (trust, verifiability, no silent corruption) is decisive.
7. Full entries returned directly
We do: query_memory returns complete entries with path:line citations. Every hit can be verified against source.
We don't: Return a minimal index first, then require a second tool call for details.
Why: Returning full entries preserves verifiability — the agent sees the exact source line for every claim. It also avoids a round-trip per useful hit. Our entries are already compact (~300 chars summary + citation); the token cost is lower than a second tool call + context switch.
8. Symbol extraction focused on what developers search for
We do: Regex-based symbol extraction (functions, classes, methods, interfaces, type aliases) with string/comment masking, multi-line signatures, and cross-file linking by symbol name. For TypeScript/JavaScript projects, an optional L2 enhancement layer uses the TS Compiler API to infer return types, resolve generics, and extract interfaces — all cached by content hash for instant reuse.
We don't: Tree-sitter AST parsing, import graphs, call graphs, or full-program type resolution across files.
Why: Our regex scanner handles 8 languages with zero dependencies, runs in <1 ms/file, and captures the declarations developers actually search for (names, signatures, generics). The optional TS layer adds semantic depth for TS/JS without native deps. Cross-file linking by name covers the most common "find related code" use case. Full-program analysis would add native binaries, 10x install size, and version fragility — for marginal gain on the remaining 5% of edge cases.
9. forget by query is aggressive; prefer ID deletion
We do: forget query deletes all experience notes with ≥0.5 token overlap.
We don't: Interactive confirmation, soft-delete/trash, or exact-match-only.
Why: Experience notes are low-stakes, high-volume, and retrieval-only. Aggressive deletion prevents stale noise from polluting search. For precision, delete by ID (shown in query_memory output).
10. TypeScript enhancement is optional, lazy, and cached
We do: L2 TS Compiler API enhancement runs async in a priority queue (P0 on fs/observed, P1 on watch, P2 on index_repo), results cached by content hash in type-cache/. Zero config — just npm i -D typescript@5 or typescript@6. Falls back to L1 regex if TS absent or disabled.
We don't: Mandatory TS, blocking enhancement, or full-program type checking.
Why: Mandatory TS would break installs for non-TS projects. Blocking enhancement would stall index_repo on large codebases. Full-program checking is 10x slower and memory-heavy. Our design: enhance what's read, cache it, never block the hot path.
Configuration
| Key | Default | Meaning |
|---|---|---|
memoryDir | .dsh-project-memory | store directory inside each indexed root |
chunkChars | 3000 | max chars per document chunk |
maxChunksPerFile | 40 | max chunks per document |
maxFileSizeMb | 50 | skip documents (incl. PDF) and code files larger than this (MB) |
maxOutputChars | 8000 | cap for query_memory result text (chars) |
tasklist.enabled | true | enable TaskBridge auto-sync (task entities from the session todo list and file reads) |
tasklist.syncHostOnAdopt | true | when select_task//task switch binds a task, push its steps to host todo/write so dsh's task list mirrors the task |
maxPdfPages | 1000 | PDF page cap when pages are not otherwise limited |
llmQueryExpansion | false | expand queries via ctx.llm before BM25 (off by default to save tokens) |
expansionCount | 6 | max expansion variants |
lazyIndexing | true | index files the moment the model reads them (fs/observed) |
autoIndexOnFirstUse | false | full scan of the current working directory on plugin load (opt-in) |
watch | true | enable the background refresh |
watchInterval | 15 | poll interval (seconds) |
tsPath | (auto) | optional absolute path to a specific typescript install; if omitted, resolves from project cwd → plugin node_modules |
enableTypeScript | true | set false to disable L2 TS enhancement entirely (L1 regex only) |
insight.* | dedupOverlap 0.7 · reinforceBand 0.65 · maxProject 100 · maxGlobalProcedures 200 · promoteConfidence 0.7 · globalPromoteTasks 3 · decayDays 90 · globalFile (auto) | v0.5 insight dedupe / reinforce / promotion / capacity / archive settings |
reflection.enabled | false | v0.5 LLM reflection, draft-only at task level (fires on task switch-away / archive). cooldownMs 1800000, maxLessonsPerReflect 3, maxDecisionsPerReflect 2 |
autoContext.enabled | true | v0.5 silent injection wrapper (entry block + relevance). Inert (full passthrough) until the host exposes a resolvable session cwd; maxTokens 400, editedMax 3 (how many recently-written "editing now" files the resident task card shows), skipEchoSelfTodo true (don't echo the task card back when the model itself maintains the task list with no newer human message; relevant insights still inject) |
Toggling features
The two most relevant switches are lazyIndexing (index a file the moment the model reads it; default on) and autoIndexOnFirstUse (full scan of the current working directory on plugin load; default off). Lazily indexed project roots are automatically registered with the watcher, so changed files stay fresh without an explicit watch_repo.
Settings live in the plugin's config object. To change them, add an override entry to your profile's cordis.patch.yml — for the web profile that is ~/.dsh/profiles/web/cordis.patch.yml:
- id: project-memory
  config:
    lazyIndexing: true          # on: index files as the model reads them (default)
    autoIndexOnFirstUse: false  # off: no upfront full scan (default)
    llmQueryExpansion: false    # off: do not spend tokens on LLM query expansion (default)
    watch: true                 # on: background refresh for watched roots (default)
    watchInterval: 15           # poll interval in seconds
    enableTypeScript: true      # on: L2 TS enhancement when TS is installed (default)
    # tsPath: /custom/path/to/typescript  # optional: force specific TS install
Only list the keys you want to change; the rest fall back to the plugin defaults. Verify the result with dsh --profile web --dump-config.
For a one-off run without editing the profile, pass the override as a CLI patch overlay:
dsh web --patch ./config.ymlwhere config.yml contains the same override block.
Development (for contributors)
These commands are for maintaining the plugin code — regular users do not need them. Installing the plugin only requires the command in Installation.
npm install
npm test          # 215 tests (166 core + 11 TaskBridge + 11 insight-store + 5 reflection + 7 auto-inject + 9 insight-actions + 6 host-contract)
License
MIT
