
dsh-voice
Full-duplex voice mode for DeepSeek Harness: streamed ASR → LLM → TTS with barge-in.
Status
v0.7.0 — press-to-talk with a live caption.
Speak into the composer mic: the assistant silences itself (playback stops, host synthesis queue drops), the running turn is cancelled (the stop-button route), and your speech is transcribed by the host (SenseVoice, CN-native simplified-Chinese ASR with punctuation + ITN) and submitted. The reply streams back as spoken audio with live captions.
Three ways to dictate:
| gesture | behaviour |
|---|---|
| tap the mic | continuous dictation; the VAD segments on trailing silence |
| hold the send key (or the mic) | records until release, slide up to discard |
hold Ctrl (configurable asr.hotkey) | same, without leaving the keyboard; Esc discards |
While a hold is open the overlay shows a live caption — the interim transcript of what has been said so far — and keeps a spinner up after release until the authoritative transcript lands.
Barge-in detection is triggered by the mic's leading speech edge. The ASR engine runs an NLMS acoustic echo canceller (see src/aec.ts) using the page's own TTS playback as the echo reference, so loud assistant audio is subtracted from the mic before the VAD — the browser-level echoCancellation constraint is kept only as a fallback when no echo reference is available.
Live caption interims are incremental: each pass sends only the audio recorded since the last pass (correlated by session header), and the host decodes a bounded sliding window per session instead of re-decoding the whole hold. Preview cost therefore stops growing with hold length.
Demo
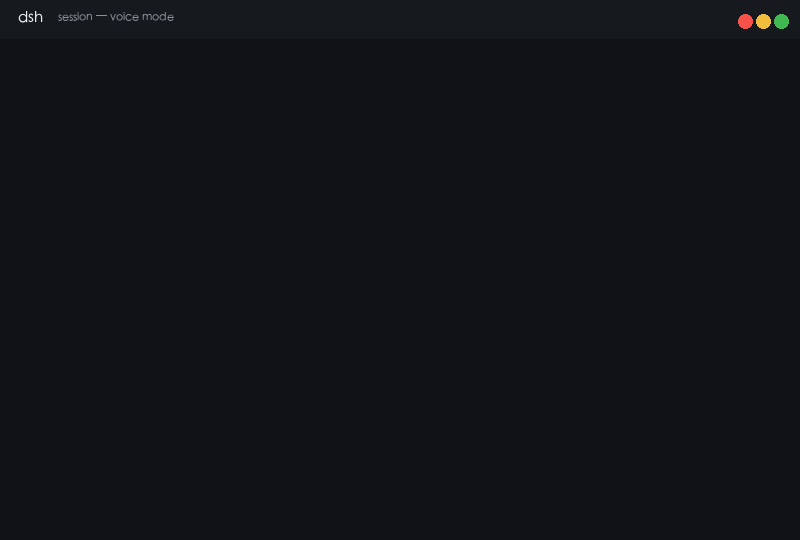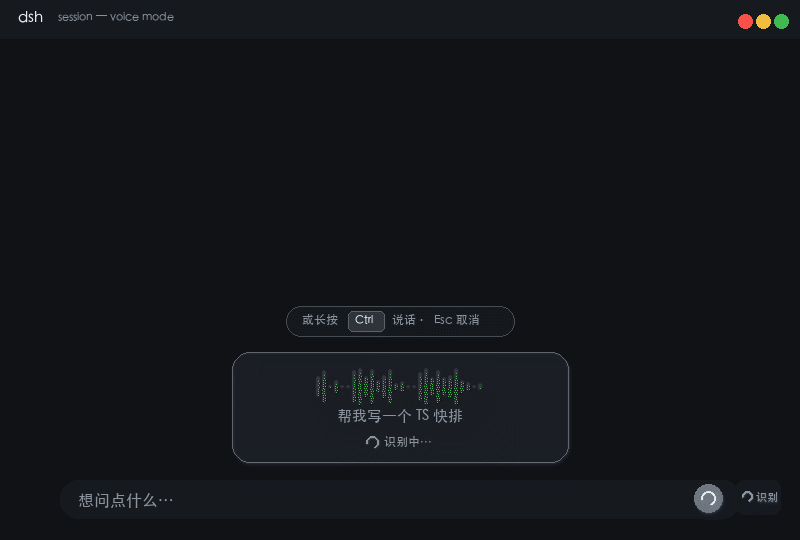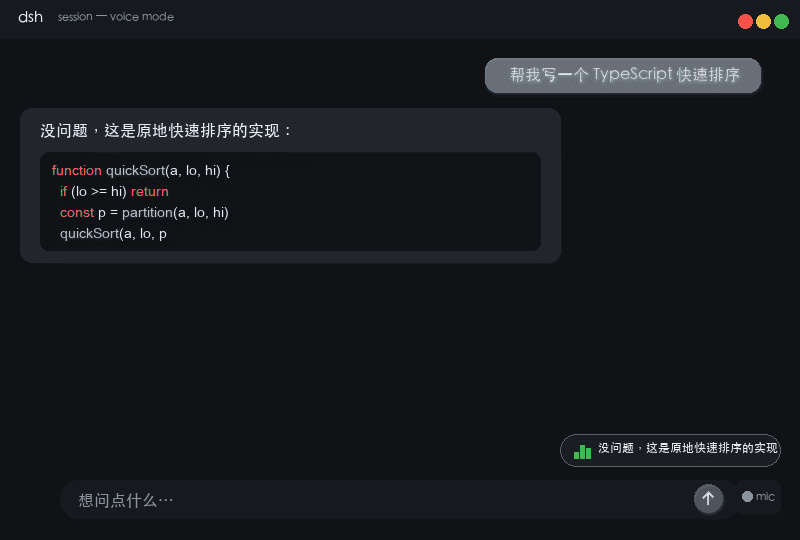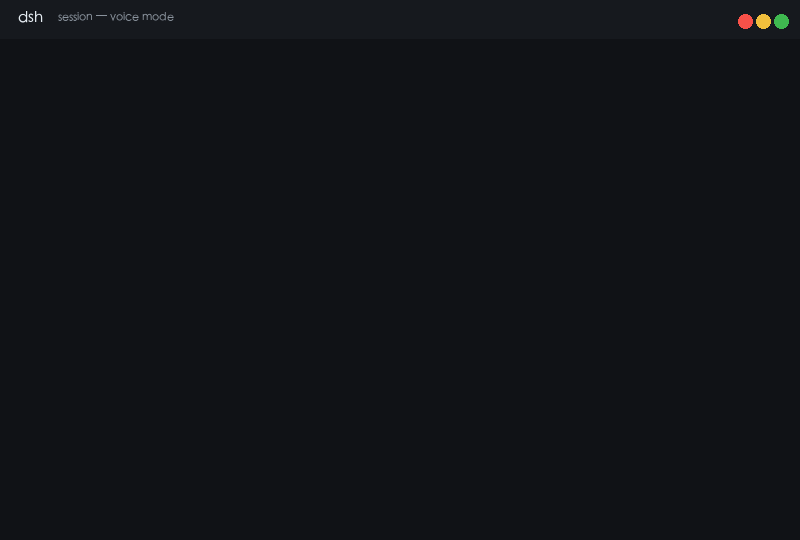
The loop: hold the composer's send key (its arrow is covered by a mic glyph), watch the live caption fill in while you speak, release into a spinner until the final transcript lands, then the reply streams back as spoken audio sentence-by-sentence — until the user's voice interrupts playback and stops the running turn mid-line (true barge-in). Ctrl does the same without leaving the keyboard.
How it works
input:  mic ──RMS endpoint detection──▶ POST /asr (raw f32 PCM)
                                           │ text (SenseVoice)
                                           ▼
        composer draft ──submit──▶ model stream ──llm/stream tap──▶ SentenceSegmenter
                                                                     │
        browser ◀── SSE /dsh-voice-api/stream ── TtsQueue (msedge-tts) ◀──┘
                  (base64 MP3 frames + caption text)

barge-in: speech edge ──▶ engine.skip() + POST /cancel (epoch bump)
+ session.cancel() when a turn is running- The
llm/streamtap is lossless: every chunk is yielded unchanged, the
segmenter only observes. The model stream is never blocked by synthesis.
- ASR runs host-side with sherpa-onnx
(Apache-2.0) running SenseVoice — the CN-native speech model that outperforms whisper on Chinese: native simplified output, punctuation, inverse text normalization (ITN) and 50+ language auto-detection. The browser only records and posts raw little-endian f32 PCM.
- Model files stream through a cache-through proxy at
/dsh-voice-api/hf and are mirrored to disk (~/.cache/dsh-voice/models/, configurable via cacheDir), so every browser/recognizer load after the first is served from local disk. Downloads resume from partial .part files when interrupted. Use npm run prefetch to warm the cache once.
- RMS endpoint detection: 16kHz getUserMedia, 2s trailing-silence cutoff,
max 30s segment, pre/post padding. Zero dependencies.
- Press-to-talk bypasses the VAD entirely. Holding the key is already the
intent, so every buffer between press and release is kept — gating on loudness there only drops quiet speech, which is indistinguishable from a broken button. Only captures below 250ms are discarded (mis-taps).
- Live caption: while a hold is open the engine re-decodes the buffer
every ~900ms and shows the interim text. SenseVoice is not a streaming model, so this is only requested while the overlay is actually on screen, and stops past 12s of audio. Interims are strictly previews: they never reach the composer draft, and an interim that lands after the release is dropped (epoch check) so it can never overwrite the final transcript.
- Barge-in is three-layered: local playback queue cleared, host
TtsQueue
epoch bumped (queued AND in-flight synthesis dropped), and the running turn cancelled when session.running is true. An aborted turn never flushes its trailing half-sentence — exactly what the user interrupted.
modelHostaccepts any HF-compatible mirror (e.g.https://hf-mirror.com
for CN networks).
API
| Route | Purpose |
|---|---|
GET /dsh-voice-api/stream | SSE; event: audio frames {sessionId, seq, text, audio(base64 MP3)} |
POST /dsh-voice-api/asr | raw little-endian f32 PCM body → {text} via SenseVoice |
POST /dsh-voice-api/cancel | {sessionId} drops queued + in-flight synthesis (epoch bump) |
GET /dsh-voice-api/config | ASR runtime config {asr: {...}} for the mic button |
GET /dsh-voice-api/hf/* | cache-through HF model proxy (mirrors to cacheDir) |
GET /dsh-voice-api/* | ping: {ok, name, enabled} |
Config (bundle patch row):
- id: voice
  name: '@haoku123/dsh-voice'
  config:
    voice: zh-CN-XiaoxiaoNeural
    cacheDir: ~/.cache/dsh-voice/models   # optional, on-disk model cache
    asr:
      model: csukuangfj/sherpa-onnx-sense-voice-zh-en-ja-ko-yue-2024-07-17
      modelHost: https://huggingface.co   # or https://hf-mirror.com
      language: auto                      # auto | zh | en | ja | ko | yue
      useItn: true                        # inverse text normalization
      autoSend: false
      mode: toggle                        # toggle | hold
      hotkey: Control                     # keyboard press-to-talk; '' disables
Model files are fetched through the proxy on first use; warm the cache once with the dsh host running:
npm run prefetch # uses http://127.0.0.1:3080 by defaultInstall
dsh plugin --profile web add <repo-url-or-path>
dsh --profile web
Note: needs Node ≥ 22.19 or ≥ 24 (node:zlib zstd APIs).
Tests
npm test                                # segmenter unit tests (pure, no network)
node test/host.integration.test.mjs     # llm/stream tap + real Edge TTS + SSE + /config
node test/bargein.test.mjs              # client inject face wiring (skipPlayback/cancelTurn)
node test/bargein-semantics.test.mjs    # aborted turn no-flush + cancel drops in-flight
node verify-client.mjs                  # client bundle registration/exports/slots/dynamic-import