
MosaicMemoryCompress

A generic, pluggable stateless dialogue compression algorithm — works with any LLM agent framework, and ships a ready-to-use adapter module for DeepSeek Harness (DSH).


LLM conversations grow linearly. MosaicMemoryCompress keeps them bounded — automatically, invisibly, and without the user ever knowing what a "Session" is.
How It Works
Your message array (R rounds, oldest → newest):

Round 1 ────→ Round (R-30)   │ Heavy zone → ALL → 2 msgs
Round (R-29) → Round (R-10)  │ Light zone → structural truncation, count unchanged
Round (R-9) ────→ Round R    │ Raw zone  → keep as-is
Steady state: constant message count — 2 + heavyStart × (messages per round), e.g. 62 messages (31 user rounds) for pure two-message rounds, whether at round 60 or round 15,000 (higher, but still constant, when tool-call rounds add messages). The compression ratio approaches 100%.
Philosophy: Alive Memory, Not a Handover Brief
The industry-standard answer to unbounded conversations is threshold summarization: when the window fills up, summarize everything into one brief and hand it to a fresh model. The conversation looks like it continues. But structurally it is *amnesia followed by reading a diary*:
- A switch moment. Memory breaks, then is rebuilt from a single summary call.
- Indiscriminate loss. The freshest instructions are paraphrased too — the
exact part that must stay vivid. In a controlled A/B experiment the brief paraphrased the user's latest instruction and silently dropped an action item ("write the key points into MEMORY").
- Invisible loss. The next model cannot know what the brief omitted, so it
cannot compensate.
MosaicMemoryCompress models the opposite: biological forgetting. A human does not remember round 3 of a 300-round conversation — they keep the lesson, the rules, the relationship. The algorithm reproduces that curve inside one message array:
recent 10 rounds   → verbatim (vivid — what you are actually working on)
rounds 10–40       → structural truncation (reasoning/args/results trimmed, text kept)
rounds 40+         → one heavy pair: identity, environment, permissions, rules
No switch moment, no reset, no length limit. The heavy zone is *semantic memory* (rules that must never be forgotten); the middle is recent episodic memory; the raw zone is the vivid present. Loss is visible: the zone structure tells the model what it no longer knows, so it can fetch detail from shadowed storage on demand.
| Threshold summarization (industry) | MosaicMemoryCompress | |
|---|---|---|
| Metaphor | amnesia + diary | continuous vivid memory |
| Continuity | resets on every compaction | never resets |
| Loss | indiscriminate, invisible | graduated, visible |
| Recent turns | paraphrased at the worst moment | always verbatim |
| Purpose | portable handover brief | unbounded human–AI dialogue |
The two philosophies complement each other: a handover brief serves cold starts and long pauses; MosaicMemoryCompress serves *staying in the conversation*. Combined with a durable host-side store (e.g. a MEMORY.md file), human and AI keep talking under the same forgetting curve indefinitely. See docs/design.md §8/§10 for the formal position-is-age model behind this design.
Quick Start
npm install mosaic-memory-compressimport { mosaicMemoryCompress, type MosaicMemoryConfig } from 'mosaic-memory-compress';
const config: MosaicMemoryConfig = {
lightStart: 10, // keep 10 most recent rounds raw (vivid)
lightWindow: 30, // compress every 30 rounds (aligned with heavy)
heavyStart: 40, // rounds before this enter the heavy zone
heavyWindow: 30, // heavy fold cadence (30-round interval)
callLLM: async (systemPrompt, userInput) => {
// Wire to OpenAI, Anthropic, or any LLM provider
const res = await openai.chat.completions.create({
model: 'gpt-4o-mini',
messages: [
{ role: 'system', content: systemPrompt },
{ role: 'user', content: userInput },
],
});
return res.choices[0].message.content ?? '';
},
};
// Call every turn — zero cost below threshold; structural light is millisecond-fast,
// Heavy folds take ~1-2s (one LLM summary call)
const compressed = await mosaicMemoryCompress(messages, config);Features
- Stateless & repeatable — no session state; call it every turn, and the output can be fed back in as input
- Zero-cost below threshold — returns immediately if no compression is due
- Anti-jitter — compression only at configurable window boundaries
- LLM-agnostic — bring your own
callLLMfunction for Heavy (OpenAI, Anthropic, local models…); light runs zero-LLM - DeepSeek Harness (DSH) adapter — ships with
dsh-module/for seamless integration; the core algorithm stays framework-agnostic - Tool-call safe — tool messages don't break round counting
- Graceful degradation — LLM failures don't block the conversation
API
mosaicMemoryCompress(messages, config)
| Param | Type | Description |
|---|---|---|
messages | Message[] | Full message array. System prompt at [0] is preserved as-is. |
config | MosaicMemoryConfig | Compression config (see below). |
| Returns | Promise<Message[]> | Compressed message array. |
MosaicMemoryConfig
| Field | Type | Default | Description | |
|---|---|---|---|---|
lightStart | number | 30 | Most recent N rounds kept raw | |
lightWindow | number | 10 | Anti-jitter: compress every N rounds | |
heavyStart | number | 50 | Rounds beyond this → Heavy zone | |
heavyWindow | number | 10 | Anti-jitter for heavy compression | |
callLLM | (sys: string, user: string) => Promise<string> | *optional* | Your LLM call function — Heavy zone only; light is structural truncation. Omit it for light-only usage | |
onCompress | `(event: CompressEvent) => void \ | Promise` | *optional* | Hook after each compression; receives the original payload for host-side archiving |
DEFAULT_CONFIG
Prefer starting from the exported defaults and overriding only what you need:
import { mosaicMemoryCompress, DEFAULT_CONFIG, type MosaicMemoryConfig } from 'mosaic-memory-compress';

const config: MosaicMemoryConfig = { ...DEFAULT_CONFIG, callLLM: async (sys, user) => { /* ... */ } };
All numeric fields must be positive integers (windows) / non-negative integers (starts), and heavyStart must be greater than lightStart. Invalid configs throw a TypeError.
Message
interface Message {
  role: 'system' | 'user' | 'assistant' | 'tool';
  content: string;
  tool_call_id?: string;
  tool_calls?: { id: string; type: 'function'; function: { name: string; arguments: string } }[];
}
Design
Read the full design document (English) or 中文设计文档.
Architecture Boundaries
MosaicMemoryCompress is intentionally stateless and lossy:
- Durable storage is the host's responsibility. The library compresses
the message array in place and never persists original payloads. Hosts that need lossless history must archive the raw messages themselves — through their own code, a database, or the host platform's persistence layer (the onCompress callback hands every compressed-away original to the host for archiving).
- Compression is lossy by design. Like any summarization approach, early
details fade progressively. That is the point: the goal is an unbounded conversation, not lossless archival. If exact retrieval of early turns matters, pair this library with a persistence layer and re-read on demand.
Integration Notes
MosaicMemoryCompress is host-agnostic and works wherever a callLLM function exists. Its primary integration reference is DeepSeek Harness (DSH) (deepseek-ai/deepseek-harness — everything is a plugin), whose task-level compaction / output retention / spill complement this library's message-level compression (roles and order preserved). ### DSH adapter: session allowlist (safety gate)
By default the adapter compresses nothing until you explicitly list session ids — a first-time trial can never touch your other conversations:
# cordis.patch.yml (or the plugin config)
config:
  sessionAllowlist:
    - fb80be2a-99aa-42e1-9de8-2f7017d2c0b6   # only this session is compressed
Use ['*'] to allow every session (the pre-allowlist behavior). Sessions not listed are a zero-cost no-op.
A denylist (sessionDenylist) always wins over the allowlist — it keeps selected sessions out of a fleet-wide rollout, e.g. one reference conversation that should stay unmanaged for diagnosis:
config:
  sessionAllowlist: ['*']              # fleet-wide
  sessionDenylist:                     # except these
    - fb80be2a-99aa-42e1-9de8-2f7017d2c0b6   # reference conversation, never compressed
A ready-to-use DSH plugin backend lives in dsh-module/ (design docs in EN/中文).
Related:
- DeepSeek Harness — the host platform
- awesome-dsh-plugin — curated DSH plugin list
- awesome-deepseek-harness — DSH ecosystem list
- design docs (EN) / 设计文档(中文) — theory and empirical case study
See the Roadmap for upcoming work.
Benchmark
A deterministic simulation (zero LLM cost, reproducible) runs the real algorithm with a rule-based pseudo-LLM. Latest sweep (default parameters):
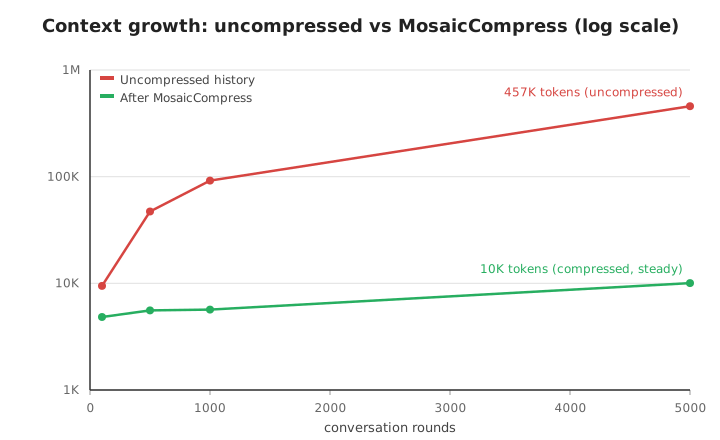
| Rounds | msgs in | msgs out | tokens in | tokens out | ratio | facts kept |
|---|---|---|---|---|---|---|
| 100 | 234 | 120 | 9,451 | 4,580 | 51.5% | 100% |
| 1,000 | 2,310 | 122 | 91,869 | 5,523 | 94.0% | 100% |
| 5,000 | 11,500 | 120 | 457,484 | 9,913 | 97.8% | 100% |
npm run bench                        # synthetic sweep: 100 / 500 / 1000 / 5000 rounds
npm run bench -- --file chat.json    # analyze your own conversation file
The file mode accepts any JSON array of messages in the library's Message shape and reports the compression ratio:
[{"role": "system", "content": "..."},
 {"role": "user", "content": "..."},
 {"role": "assistant", "content": "..."}]
See benchmark/README.md for the full method, data generation, findings, limitations, and the real-LLM spot check (npm run bench:real — DeepSeek V4 Flash, <$0.01, 5/5 facts retained).
Development
# Run tests (zero LLM cost — uses mock responses)
npm test

# Type-check the whole project
npm run typecheck

# Or directly:
npx tsx tests/index.test.ts
License
MIT — TuringCorp | [email protected]
